{
"cells": [
{
"cell_type": "markdown",
"id": "3c45c9fc",
"metadata": {
"origin_pos": 0
},
"source": [
"# Nhận dạng giống chó (Chó ImageNet) trên Kaggle\n",
"\n",
"Trong phần này, chúng tôi sẽ thực hành vấn đề nhận dạng giống chó trên Kaggle. (**Địa chỉ web của cuộc thi này là https://www.kaggle.com/c/dog-breed-identification **) \n",
"\n",
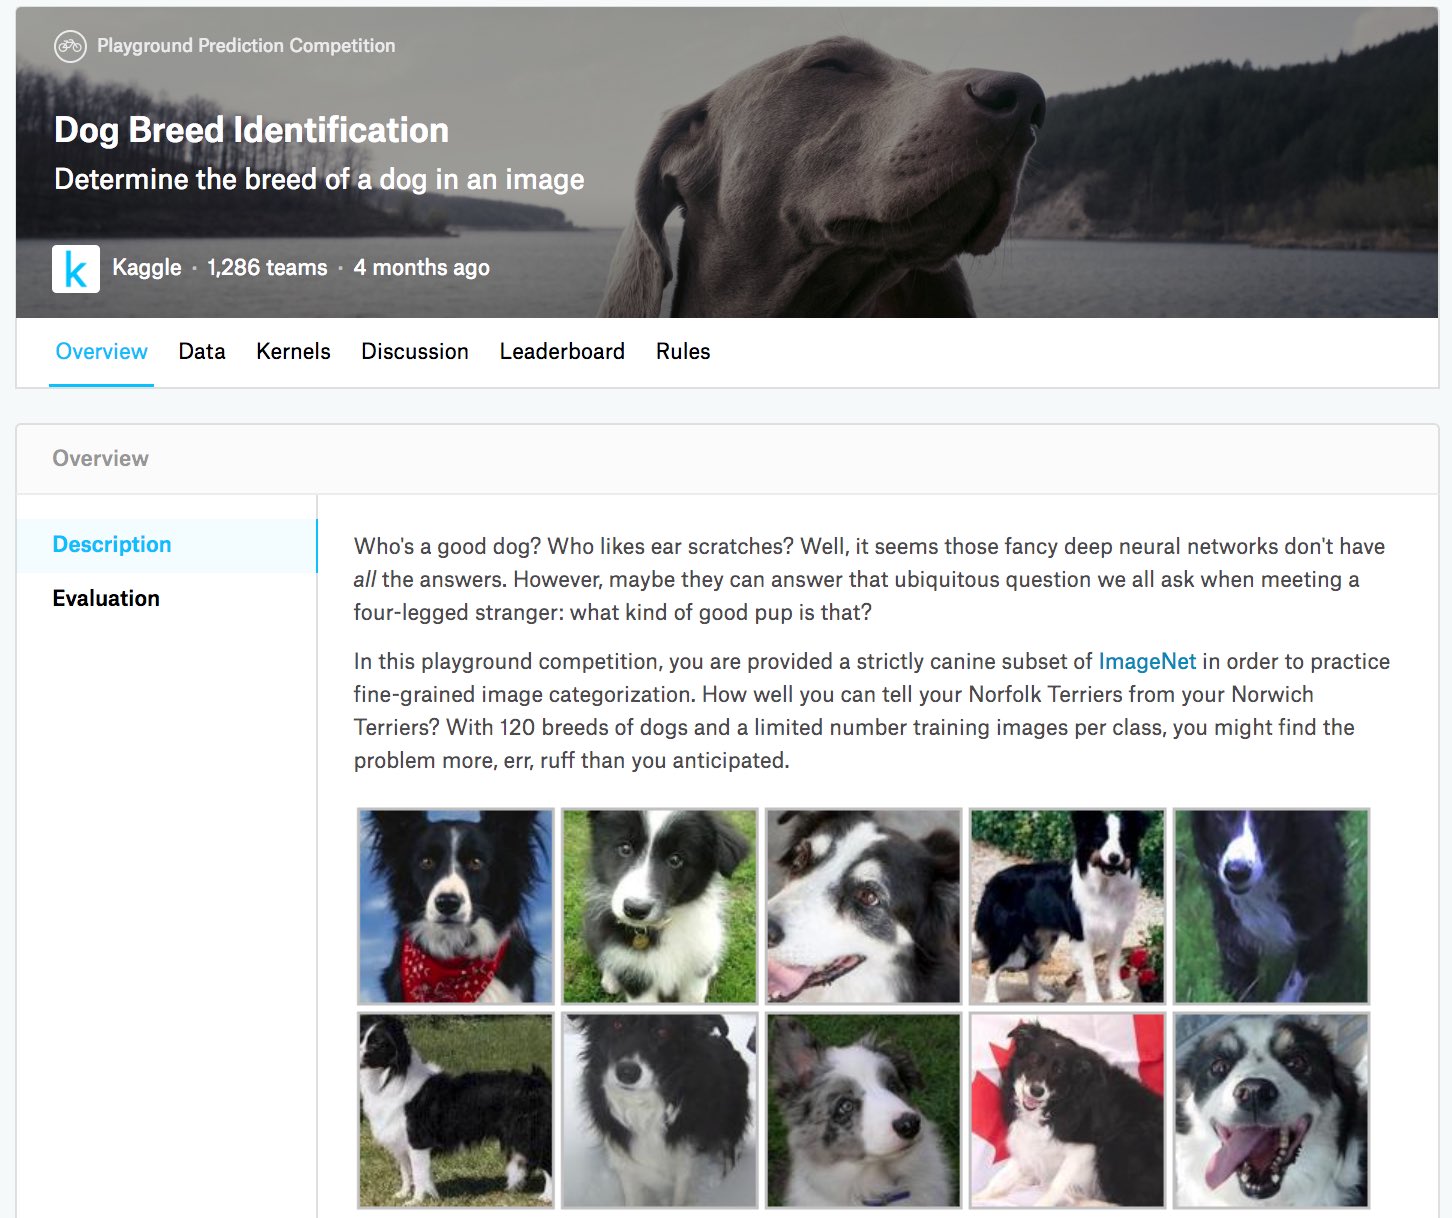
"Trong cuộc thi này, 120 giống chó khác nhau sẽ được công nhận. Trên thực tế, tập dữ liệu cho cuộc thi này là một tập hợp con của tập dữ liệu ImageNet. Không giống như các hình ảnh trong tập dữ liệu CIFAR-10 trong :numref:`sec_kaggle_cifar10`, các hình ảnh trong tập dữ liệu ImageNet đều cao hơn và rộng hơn ở các kích thước khác nhau. :numref:`fig_kaggle_dog` hiển thị thông tin trên trang web của đối thủ. Bạn cần một tài khoản Kaggle để gửi kết quả của mình. \n",
"\n",
"\n",
":width:`400px`\n",
":label:`fig_kaggle_dog`\n"
]
},
{
"cell_type": "code",
"execution_count": 1,
"id": "cb1abb3c",
"metadata": {
"execution": {
"iopub.execute_input": "2022-04-26T10:53:12.082520Z",
"iopub.status.busy": "2022-04-26T10:53:12.081983Z",
"iopub.status.idle": "2022-04-26T10:53:17.374839Z",
"shell.execute_reply": "2022-04-26T10:53:17.373825Z"
},
"origin_pos": 1,
"tab": [
"mxnet"
]
},
"outputs": [],
"source": [
"import os\n",
"from mxnet import autograd, gluon, init, npx\n",
"from mxnet.gluon import nn\n",
"from d2l import mxnet as d2l\n",
"\n",
"npx.set_np()"
]
},
{
"cell_type": "markdown",
"id": "ff86803c",
"metadata": {
"origin_pos": 3
},
"source": [
"## Lấy và tổ chức tập dữ liệu\n",
"\n",
"Tập dữ liệu cạnh tranh được chia thành một bộ đào tạo và một bộ thử nghiệm, trong đó có 10222 và 10357 hình ảnh JPEG của ba kênh RGB (màu), tương ứng. Trong số các tập dữ liệu huấn luyện, có 120 giống chó như Labradors, Poodles, Dachshunds, Samoyeds, Huskies, Chihuahua, và Yorkshire Terriers. \n",
"\n",
"### Tải xuống tập dữ liệu\n",
"\n",
"Sau khi đăng nhập vào Kaggle, bạn có thể nhấp vào tab “Dữ liệu” trên trang web cạnh tranh được hiển thị trong :numref:`fig_kaggle_dog` và tải xuống tập dữ liệu bằng cách nhấp vào nút “Tải xuống tất cả”. Sau khi giải nén tệp đã tải xuống trong `../data`, bạn sẽ tìm thấy toàn bộ tập dữ liệu trong các đường dẫn sau: \n",
"\n",
"* .. /data/dog-breed-identification/labels.csv\n",
"* .. /data/dog-breed-identification/sample_submission.csv\n",
"* .. /data/dog-breed-identification/tàu\n",
"* .. /data/dog-breed-identification/test\n",
"\n",
"Bạn có thể nhận thấy rằng cấu trúc trên tương tự như cấu trúc của cuộc thi CIFAR-10 trong :numref:`sec_kaggle_cifar10`, trong đó các thư mục `train/` và `test/` chứa các hình ảnh huấn luyện và thử nghiệm hình ảnh chó, và `labels.csv` chứa nhãn cho hình ảnh đào tạo. Tương tự, để bắt đầu dễ dàng hơn, [**chúng tôi cung cấp một mẫu nhỏ của bộ dữ liệu**] được đề cập ở trên: `train_valid_test_tiny.zip`. Nếu bạn định sử dụng bộ dữ liệu đầy đủ cho cuộc thi Kaggle, bạn cần thay đổi biến `demo` bên dưới thành `False`.\n"
]
},
{
"cell_type": "code",
"execution_count": 2,
"id": "5391b6ff",
"metadata": {
"execution": {
"iopub.execute_input": "2022-04-26T10:53:17.380197Z",
"iopub.status.busy": "2022-04-26T10:53:17.379595Z",
"iopub.status.idle": "2022-04-26T10:53:18.434513Z",
"shell.execute_reply": "2022-04-26T10:53:18.433456Z"
},
"origin_pos": 4,
"tab": [
"mxnet"
]
},
"outputs": [
{
"name": "stdout",
"output_type": "stream",
"text": [
"Downloading ../data/kaggle_dog_tiny.zip from http://d2l-data.s3-accelerate.amazonaws.com/kaggle_dog_tiny.zip...\n"
]
}
],
"source": [
"#@save\n",
"d2l.DATA_HUB['dog_tiny'] = (d2l.DATA_URL + 'kaggle_dog_tiny.zip',\n",
" '0cb91d09b814ecdc07b50f31f8dcad3e81d6a86d')\n",
"\n",
"# If you use the full dataset downloaded for the Kaggle competition, change\n",
"# the variable below to `False`\n",
"demo = True\n",
"if demo:\n",
" data_dir = d2l.download_extract('dog_tiny')\n",
"else:\n",
" data_dir = os.path.join('..', 'data', 'dog-breed-identification')"
]
},
{
"cell_type": "markdown",
"id": "03475aa1",
"metadata": {
"origin_pos": 5
},
"source": [
"### [**Torganizing the Dataset**]\n",
"\n",
"Chúng ta có thể sắp xếp tập dữ liệu tương tự như những gì chúng ta đã làm trong :numref:`sec_kaggle_cifar10`, cụ thể là tách ra một bộ xác thực từ bộ đào tạo ban đầu và di chuyển hình ảnh vào các thư mục con được nhóm theo nhãn. \n",
"\n",
"Chức năng `reorg_dog_data` dưới đây đọc các nhãn dữ liệu đào tạo, tách bộ xác thực và tổ chức bộ đào tạo.\n"
]
},
{
"cell_type": "code",
"execution_count": 3,
"id": "f9e99490",
"metadata": {
"execution": {
"iopub.execute_input": "2022-04-26T10:53:18.440408Z",
"iopub.status.busy": "2022-04-26T10:53:18.439685Z",
"iopub.status.idle": "2022-04-26T10:53:18.831543Z",
"shell.execute_reply": "2022-04-26T10:53:18.830542Z"
},
"origin_pos": 6,
"tab": [
"mxnet"
]
},
"outputs": [],
"source": [
"def reorg_dog_data(data_dir, valid_ratio):\n",
" labels = d2l.read_csv_labels(os.path.join(data_dir, 'labels.csv'))\n",
" d2l.reorg_train_valid(data_dir, labels, valid_ratio)\n",
" d2l.reorg_test(data_dir)\n",
"\n",
"\n",
"batch_size = 32 if demo else 128\n",
"valid_ratio = 0.1\n",
"reorg_dog_data(data_dir, valid_ratio)"
]
},
{
"cell_type": "markdown",
"id": "6677d499",
"metadata": {
"origin_pos": 7
},
"source": [
"## [**Image Augmentation**]\n",
"\n",
"Nhớ lại rằng tập dữ liệu giống chó này là một tập hợp con của tập dữ liệu ImageNet, có hình ảnh lớn hơn của tập dữ liệu CIFAR-10 vào năm :numref:`sec_kaggle_cifar10`. Sau đây liệt kê một vài thao tác nâng hình ảnh có thể hữu ích cho các hình ảnh tương đối lớn hơn.\n"
]
},
{
"cell_type": "code",
"execution_count": 4,
"id": "f4ac3ae5",
"metadata": {
"execution": {
"iopub.execute_input": "2022-04-26T10:53:18.835961Z",
"iopub.status.busy": "2022-04-26T10:53:18.835425Z",
"iopub.status.idle": "2022-04-26T10:53:18.842805Z",
"shell.execute_reply": "2022-04-26T10:53:18.841863Z"
},
"origin_pos": 8,
"tab": [
"mxnet"
]
},
"outputs": [],
"source": [
"transform_train = gluon.data.vision.transforms.Compose([\n",
" # Randomly crop the image to obtain an image with an area of 0.08 to 1 of\n",
" # the original area and height-to-width ratio between 3/4 and 4/3. Then,\n",
" # scale the image to create a new 224 x 224 image\n",
" gluon.data.vision.transforms.RandomResizedCrop(224, scale=(0.08, 1.0),\n",
" ratio=(3.0/4.0, 4.0/3.0)),\n",
" gluon.data.vision.transforms.RandomFlipLeftRight(),\n",
" # Randomly change the brightness, contrast, and saturation\n",
" gluon.data.vision.transforms.RandomColorJitter(brightness=0.4,\n",
" contrast=0.4,\n",
" saturation=0.4),\n",
" # Add random noise\n",
" gluon.data.vision.transforms.RandomLighting(0.1),\n",
" gluon.data.vision.transforms.ToTensor(),\n",
" # Standardize each channel of the image\n",
" gluon.data.vision.transforms.Normalize([0.485, 0.456, 0.406],\n",
" [0.229, 0.224, 0.225])])"
]
},
{
"cell_type": "markdown",
"id": "bbfe3b4c",
"metadata": {
"origin_pos": 10
},
"source": [
"Trong quá trình dự đoán, chúng tôi chỉ sử dụng các thao tác tiền xử lý hình ảnh mà không có tính ngẫu nhiên.\n"
]
},
{
"cell_type": "code",
"execution_count": 5,
"id": "8ad83dca",
"metadata": {
"execution": {
"iopub.execute_input": "2022-04-26T10:53:18.846437Z",
"iopub.status.busy": "2022-04-26T10:53:18.845992Z",
"iopub.status.idle": "2022-04-26T10:53:18.852751Z",
"shell.execute_reply": "2022-04-26T10:53:18.852070Z"
},
"origin_pos": 11,
"tab": [
"mxnet"
]
},
"outputs": [],
"source": [
"transform_test = gluon.data.vision.transforms.Compose([\n",
" gluon.data.vision.transforms.Resize(256),\n",
" # Crop a 224 x 224 square area from the center of the image\n",
" gluon.data.vision.transforms.CenterCrop(224),\n",
" gluon.data.vision.transforms.ToTensor(),\n",
" gluon.data.vision.transforms.Normalize([0.485, 0.456, 0.406],\n",
" [0.229, 0.224, 0.225])])"
]
},
{
"cell_type": "markdown",
"id": "619057e5",
"metadata": {
"origin_pos": 13
},
"source": [
"## [**Đọc dữ liệu**]\n",
"\n",
"Như trong :numref:`sec_kaggle_cifar10`, chúng ta có thể đọc tập dữ liệu có tổ chức bao gồm các tệp hình ảnh thô.\n"
]
},
{
"cell_type": "code",
"execution_count": 6,
"id": "0aa63d01",
"metadata": {
"execution": {
"iopub.execute_input": "2022-04-26T10:53:18.857180Z",
"iopub.status.busy": "2022-04-26T10:53:18.856498Z",
"iopub.status.idle": "2022-04-26T10:53:18.881244Z",
"shell.execute_reply": "2022-04-26T10:53:18.880300Z"
},
"origin_pos": 14,
"tab": [
"mxnet"
]
},
"outputs": [],
"source": [
"train_ds, valid_ds, train_valid_ds, test_ds = [\n",
" gluon.data.vision.ImageFolderDataset(\n",
" os.path.join(data_dir, 'train_valid_test', folder))\n",
" for folder in ('train', 'valid', 'train_valid', 'test')]"
]
},
{
"cell_type": "markdown",
"id": "a6359184",
"metadata": {
"origin_pos": 16
},
"source": [
"Dưới đây chúng ta tạo các trường hợp lặp dữ liệu giống như trong :numref:`sec_kaggle_cifar10`.\n"
]
},
{
"cell_type": "code",
"execution_count": 7,
"id": "e19b62e0",
"metadata": {
"execution": {
"iopub.execute_input": "2022-04-26T10:53:18.886286Z",
"iopub.status.busy": "2022-04-26T10:53:18.885733Z",
"iopub.status.idle": "2022-04-26T10:53:18.891108Z",
"shell.execute_reply": "2022-04-26T10:53:18.890473Z"
},
"origin_pos": 17,
"tab": [
"mxnet"
]
},
"outputs": [],
"source": [
"train_iter, train_valid_iter = [gluon.data.DataLoader(\n",
" dataset.transform_first(transform_train), batch_size, shuffle=True,\n",
" last_batch='discard') for dataset in (train_ds, train_valid_ds)]\n",
"\n",
"valid_iter = gluon.data.DataLoader(\n",
" valid_ds.transform_first(transform_test), batch_size, shuffle=False,\n",
" last_batch='discard')\n",
"\n",
"test_iter = gluon.data.DataLoader(\n",
" test_ds.transform_first(transform_test), batch_size, shuffle=False,\n",
" last_batch='keep')"
]
},
{
"cell_type": "markdown",
"id": "cbd51557",
"metadata": {
"origin_pos": 19
},
"source": [
"## [**Tinh chỉnh một mô hình Pretrained Model**]\n",
"\n",
"Một lần nữa, tập dữ liệu cho cuộc thi này là một tập hợp con của tập dữ liệu ImageNet. Do đó, chúng ta có thể sử dụng phương pháp được thảo luận trong :numref:`sec_fine_tuning` để chọn một mô hình được đào tạo trước trên tập dữ liệu ImageNet đầy đủ và sử dụng nó để trích xuất các tính năng hình ảnh được đưa vào mạng đầu ra quy mô nhỏ tùy chỉnh. API cấp cao của các framework deep learning cung cấp một loạt các mô hình được đào tạo trước trên tập dữ liệu ImageNet. Ở đây, chúng tôi chọn một mô hình ResNet-34 được đào tạo trước, nơi chúng tôi chỉ cần sử dụng lại đầu vào của lớp đầu ra của mô hình này (tức là các tính năng được trích xuất). Sau đó, chúng ta có thể thay thế lớp đầu ra ban đầu bằng một mạng đầu ra tùy chỉnh nhỏ có thể được đào tạo, chẳng hạn như xếp chồng hai lớp được kết nối hoàn toàn. Khác với thí nghiệm trong :numref:`sec_fine_tuning`, những điều sau đây không đào tạo lại mô hình được đào tạo trước được sử dụng để trích xuất tính năng. Điều này làm giảm thời gian đào tạo và bộ nhớ để lưu trữ gradient. \n",
"\n",
"Nhớ lại rằng chúng tôi chuẩn hóa hình ảnh bằng cách sử dụng phương tiện và độ lệch chuẩn của ba kênh RGB cho tập dữ liệu ImageNet đầy đủ. Trên thực tế, điều này cũng phù hợp với hoạt động tiêu chuẩn hóa bởi mô hình được đào tạo trước trên ImageNet.\n"
]
},
{
"cell_type": "code",
"execution_count": 8,
"id": "98d7dfb0",
"metadata": {
"execution": {
"iopub.execute_input": "2022-04-26T10:53:18.894890Z",
"iopub.status.busy": "2022-04-26T10:53:18.894114Z",
"iopub.status.idle": "2022-04-26T10:53:18.901373Z",
"shell.execute_reply": "2022-04-26T10:53:18.900426Z"
},
"origin_pos": 20,
"tab": [
"mxnet"
]
},
"outputs": [],
"source": [
"def get_net(devices):\n",
" finetune_net = gluon.model_zoo.vision.resnet34_v2(pretrained=True)\n",
" # Define a new output network\n",
" finetune_net.output_new = nn.HybridSequential(prefix='')\n",
" finetune_net.output_new.add(nn.Dense(256, activation='relu'))\n",
" # There are 120 output categories\n",
" finetune_net.output_new.add(nn.Dense(120))\n",
" # Initialize the output network\n",
" finetune_net.output_new.initialize(init.Xavier(), ctx=devices)\n",
" # Distribute the model parameters to the CPUs or GPUs used for computation\n",
" finetune_net.collect_params().reset_ctx(devices)\n",
" return finetune_net"
]
},
{
"cell_type": "markdown",
"id": "34513a44",
"metadata": {
"origin_pos": 22
},
"source": [
"Trước khi [** tính lấu**], trước tiên chúng ta có được đầu vào của lớp đầu ra của mô hình được đào tạo sẵn, tức là tính năng trích xuất. Sau đó, chúng tôi sử dụng tính năng này làm đầu vào cho mạng đầu ra tùy chỉnh nhỏ của chúng tôi để tính toán tổn thất.\n"
]
},
{
"cell_type": "code",
"execution_count": 9,
"id": "ac1b1c8a",
"metadata": {
"execution": {
"iopub.execute_input": "2022-04-26T10:53:18.905115Z",
"iopub.status.busy": "2022-04-26T10:53:18.904869Z",
"iopub.status.idle": "2022-04-26T10:53:18.913011Z",
"shell.execute_reply": "2022-04-26T10:53:18.911920Z"
},
"origin_pos": 23,
"tab": [
"mxnet"
]
},
"outputs": [],
"source": [
"loss = gluon.loss.SoftmaxCrossEntropyLoss()\n",
"\n",
"def evaluate_loss(data_iter, net, devices):\n",
" l_sum, n = 0.0, 0\n",
" for features, labels in data_iter:\n",
" X_shards, y_shards = d2l.split_batch(features, labels, devices)\n",
" output_features = [net.features(X_shard) for X_shard in X_shards]\n",
" outputs = [net.output_new(feature) for feature in output_features]\n",
" ls = [loss(output, y_shard).sum() for output, y_shard\n",
" in zip(outputs, y_shards)]\n",
" l_sum += sum([float(l.sum()) for l in ls])\n",
" n += labels.size\n",
" return l_sum / n"
]
},
{
"cell_type": "markdown",
"id": "2e8ef024",
"metadata": {
"origin_pos": 25
},
"source": [
"## Xác định [**chức năng đào tạo**]\n",
"\n",
"Chúng tôi sẽ chọn mô hình và điều chỉnh các siêu tham số theo hiệu suất của mô hình trên bộ xác thực. Chức năng đào tạo mô hình `train` chỉ lặp lại các thông số của mạng đầu ra tùy chỉnh nhỏ.\n"
]
},
{
"cell_type": "code",
"execution_count": 10,
"id": "d54b47a0",
"metadata": {
"execution": {
"iopub.execute_input": "2022-04-26T10:53:18.916539Z",
"iopub.status.busy": "2022-04-26T10:53:18.916031Z",
"iopub.status.idle": "2022-04-26T10:53:18.932167Z",
"shell.execute_reply": "2022-04-26T10:53:18.930977Z"
},
"origin_pos": 26,
"tab": [
"mxnet"
]
},
"outputs": [],
"source": [
"def train(net, train_iter, valid_iter, num_epochs, lr, wd, devices, lr_period,\n",
" lr_decay):\n",
" # Only train the small custom output network\n",
" trainer = gluon.Trainer(net.output_new.collect_params(), 'sgd',\n",
" {'learning_rate': lr, 'momentum': 0.9, 'wd': wd})\n",
" num_batches, timer = len(train_iter), d2l.Timer()\n",
" legend = ['train loss']\n",
" if valid_iter is not None:\n",
" legend.append('valid loss')\n",
" animator = d2l.Animator(xlabel='epoch', xlim=[1, num_epochs],\n",
" legend=legend)\n",
" for epoch in range(num_epochs):\n",
" metric = d2l.Accumulator(2)\n",
" if epoch > 0 and epoch % lr_period == 0:\n",
" trainer.set_learning_rate(trainer.learning_rate * lr_decay)\n",
" for i, (features, labels) in enumerate(train_iter):\n",
" timer.start()\n",
" X_shards, y_shards = d2l.split_batch(features, labels, devices)\n",
" output_features = [net.features(X_shard) for X_shard in X_shards]\n",
" with autograd.record():\n",
" outputs = [net.output_new(feature)\n",
" for feature in output_features]\n",
" ls = [loss(output, y_shard).sum() for output, y_shard\n",
" in zip(outputs, y_shards)]\n",
" for l in ls:\n",
" l.backward()\n",
" trainer.step(batch_size)\n",
" metric.add(sum([float(l.sum()) for l in ls]), labels.shape[0])\n",
" timer.stop()\n",
" if (i + 1) % (num_batches // 5) == 0 or i == num_batches - 1:\n",
" animator.add(epoch + (i + 1) / num_batches,\n",
" (metric[0] / metric[1], None))\n",
" if valid_iter is not None:\n",
" valid_loss = evaluate_loss(valid_iter, net, devices)\n",
" animator.add(epoch + 1, (None, valid_loss))\n",
" measures = f'train loss {metric[0] / metric[1]:.3f}'\n",
" if valid_iter is not None:\n",
" measures += f', valid loss {valid_loss:.3f}'\n",
" print(measures + f'\\n{metric[1] * num_epochs / timer.sum():.1f}'\n",
" f' examples/sec on {str(devices)}')"
]
},
{
"cell_type": "markdown",
"id": "9bae68be",
"metadata": {
"origin_pos": 28
},
"source": [
"## [**Đào tạo và xác thực mô hình**]\n",
"\n",
"Bây giờ chúng ta có thể đào tạo và xác thực mô hình. Các siêu tham số sau đây đều có thể điều chỉnh được. Ví dụ, số lượng kỷ nguyên có thể được tăng lên. Bởi vì `lr_period` và `lr_decay` được đặt thành 2 và 0,9, tương ứng, tỷ lệ học tập của thuật toán tối ưu hóa sẽ được nhân với 0,9 sau mỗi 2 kỷ nguyên.\n"
]
},
{
"cell_type": "code",
"execution_count": 11,
"id": "53b4261b",
"metadata": {
"execution": {
"iopub.execute_input": "2022-04-26T10:53:18.936687Z",
"iopub.status.busy": "2022-04-26T10:53:18.936068Z",
"iopub.status.idle": "2022-04-26T10:55:27.882561Z",
"shell.execute_reply": "2022-04-26T10:55:27.881873Z"
},
"origin_pos": 29,
"tab": [
"mxnet"
]
},
"outputs": [
{
"name": "stdout",
"output_type": "stream",
"text": [
"train loss 0.934, valid loss 0.889\n",
"140.6 examples/sec on [gpu(0), gpu(1)]\n"
]
},
{
"data": {
"image/svg+xml": [
"\n",
"\n",
"\n"
],
"text/plain": [
""
]
},
"metadata": {
"needs_background": "light"
},
"output_type": "display_data"
}
],
"source": [
"devices, num_epochs, lr, wd = d2l.try_all_gpus(), 10, 5e-3, 1e-4\n",
"lr_period, lr_decay, net = 2, 0.9, get_net(devices)\n",
"net.hybridize()\n",
"train(net, train_iter, valid_iter, num_epochs, lr, wd, devices, lr_period,\n",
" lr_decay)"
]
},
{
"cell_type": "markdown",
"id": "40cef812",
"metadata": {
"origin_pos": 31
},
"source": [
"## [**Phân loại bộ thử nghiệm**] và gửi kết quả trên Kaggle\n",
"\n",
"Tương tự như bước cuối cùng trong :numref:`sec_kaggle_cifar10`, cuối cùng tất cả dữ liệu được dán nhãn (bao gồm cả bộ xác thực) được sử dụng để đào tạo mô hình và phân loại bộ thử nghiệm. Chúng tôi sẽ sử dụng mạng đầu ra tùy chỉnh được đào tạo để phân loại.\n"
]
},
{
"cell_type": "code",
"execution_count": 12,
"id": "cc65bc9e",
"metadata": {
"execution": {
"iopub.execute_input": "2022-04-26T10:55:27.885889Z",
"iopub.status.busy": "2022-04-26T10:55:27.885383Z",
"iopub.status.idle": "2022-04-26T10:58:07.922888Z",
"shell.execute_reply": "2022-04-26T10:58:07.922155Z"
},
"origin_pos": 32,
"tab": [
"mxnet"
]
},
"outputs": [
{
"name": "stdout",
"output_type": "stream",
"text": [
"train loss 0.858\n",
"110.1 examples/sec on [gpu(0), gpu(1)]\n"
]
},
{
"data": {
"image/svg+xml": [
"\n",
"\n",
"\n"
],
"text/plain": [
""
]
},
"metadata": {
"needs_background": "light"
},
"output_type": "display_data"
}
],
"source": [
"net = get_net(devices)\n",
"net.hybridize()\n",
"train(net, train_valid_iter, None, num_epochs, lr, wd, devices, lr_period,\n",
" lr_decay)\n",
"\n",
"preds = []\n",
"for data, label in test_iter:\n",
" output_features = net.features(data.as_in_ctx(devices[0]))\n",
" output = npx.softmax(net.output_new(output_features))\n",
" preds.extend(output.asnumpy())\n",
"ids = sorted(os.listdir(\n",
" os.path.join(data_dir, 'train_valid_test', 'test', 'unknown')))\n",
"with open('submission.csv', 'w') as f:\n",
" f.write('id,' + ','.join(train_valid_ds.synsets) + '\\n')\n",
" for i, output in zip(ids, preds):\n",
" f.write(i.split('.')[0] + ',' + ','.join(\n",
" [str(num) for num in output]) + '\\n')"
]
},
{
"cell_type": "markdown",
"id": "17681c1c",
"metadata": {
"origin_pos": 34
},
"source": [
"Đoạn mã trên sẽ tạo ra một tập tin `submission.csv` để gửi cho Kaggle theo cách tương tự được mô tả trong :numref:`sec_kaggle_house`. \n",
"\n",
"## Tóm tắt\n",
"\n",
"* Hình ảnh trong tập dữ liệu ImageNet lớn hơn (với các kích thước khác nhau) so với hình ảnh CIFAR-10. Chúng tôi có thể sửa đổi các thao tác nâng hình ảnh cho các tác vụ trên một tập dữ liệu khác.\n",
"* Để phân loại một tập hợp con của tập dữ liệu ImageNet, chúng ta có thể tận dụng các mô hình được đào tạo trước trên tập dữ liệu ImageNet đầy đủ để trích xuất các tính năng và chỉ đào tạo mạng đầu ra quy mô nhỏ tùy chỉnh. Điều này sẽ dẫn đến thời gian tính toán và chi phí bộ nhớ ít hơn.\n",
"\n",
"## Bài tập\n",
"\n",
"1. Khi sử dụng bộ dữ liệu cạnh tranh Kaggle đầy đủ, bạn có thể đạt được kết quả gì khi tăng `batch_size` (kích thước lô) và `num_epochs` (số thời đại) trong khi đặt một số siêu tham số khác là `lr = 0.01`, `lr_period = 10` và `lr_decay = 0.1`?\n",
"1. Bạn có nhận được kết quả tốt hơn nếu bạn sử dụng một mô hình được đào tạo sâu hơn? Làm thế nào để bạn điều chỉnh các siêu tham số? Bạn có thể cải thiện hơn nữa kết quả?\n"
]
},
{
"cell_type": "markdown",
"id": "800adb85",
"metadata": {
"origin_pos": 35,
"tab": [
"mxnet"
]
},
"source": [
"[Discussions](https://discuss.d2l.ai/t/380)\n"
]
}
],
"metadata": {
"language_info": {
"name": "python"
}
},
"nbformat": 4,
"nbformat_minor": 5
}